By the manufacturing analytics team at AdaptNXT.
If you have ever looked at an OEE score and thought "72% — that means 28% of our production potential is being wasted," you are thinking about it correctly. But the next question — the one that actually drives improvement — is: where is that 28% going?
The Six Big Losses framework answers that question. Developed by Seiichi Nakajima as part of Total Productive Maintenance (TPM), it provides an exhaustive classification of every possible production loss into six categories. Every minute your machine is not producing good parts at full speed is explained by one of these six losses. Every one of them has a distinct cause, a distinct detection method, and a distinct improvement strategy.
Need an Architect's Assessment?
Speak directly with a senior AdaptNXT solutions architect about your system constraints, timeline, and production feasibility.
This guide explains each of the six losses, how automated IoT monitoring catches them automatically (including the ones manual tracking consistently misses), and what you do about each one.
Key Takeaways
- Understand the core principles and semantic structure for better SEO.
- Implement real-time monitoring and scalable frameworks to drive ROI.
- Adopt a robust governance and compliance strategy.
Summary Overview
| Concept | Impact |
|---|---|
| Efficiency | Reduces manual effort and accelerates processing times. |
| Quality | Minimizes errors and ensures consistent output. |
| Scalability | Enables seamless growth without proportional cost increases. |
How the Six Big Losses Map to OEE
The Six Big Losses are grouped across the three OEE factors:
| OEE Factor | Loss Category | Example |
|---|---|---|
| Availability | 1. Unplanned Stops (Breakdowns) | Spindle bearing failure, hydraulic seal burst |
| 2. Planned Stops (Setup & Adjustments) | Die changeover, tooling swap, machine warm-up | |
| Performance | 3. Small Stops (Idling & Minor Stoppages) | Sensor trip, part jam cleared in 30 seconds |
| 4. Reduced Speed (Slow Cycles) | Machine running at 70% of rated speed due to worn tooling | |
| Quality | 5. Startup Rejects | First 20 parts scrapped while injection mould heats up |
| 6. Production Defects | Dimensional deviation during steady-state production |
Loss 1: Unplanned Stops (Breakdowns)
What It Is
An unplanned stop is any event that causes production to halt unexpectedly — a machine failure, a component breakdown, or a process fault that requires corrective action before production can resume. This is the most visible and emotionally disruptive of all six losses: alarms sound, supervisors run, production schedules collapse.
Real-World Examples
- CNC spindle bearing fails during a production run — machine down for 4 hours while bearings are sourced and replaced
- Hydraulic pump overheats and triggers a safety shutdown — 90 minutes to cool and recommission
- Electrical fault trips the main breaker — 45 minutes for the electrician to diagnose and reset
- PLC program fault after a power fluctuation — 30 minutes to restart and verify
How Real-Time Monitoring Detects It
When a machine stops unexpectedly, the edge gateway detects the state change within seconds (via current-clamp signature drop or PLC state register change) and immediately timestamps the event as "Unplanned Stop." The OEE dashboard reflects the lost Availability in real time and sends an alert to the maintenance team — before a supervisor even has a chance to walk over.
More powerfully: ML-based anomaly detection running on the edge gateway can detect the early signatures of bearing wear (increasing vibration amplitude at characteristic frequencies), hydraulic degradation (rising temperature trend), or electrical instability (unusual current signatures) — and alert maintenance teams 24–72 hours before the breakdown occurs. This converts unplanned stops into planned maintenance events.
Improvement Levers
- Predictive maintenance: condition monitoring with vibration, temperature, and current sensors
- Autonomous maintenance (TPM Pillar 1): operators trained to detect abnormalities early
- Focused improvement on recurring breakdown patterns identified by OEE loss analysis
Loss 2: Planned Stops (Setup & Adjustments)
What It Is
Planned stops are scheduled periods when the machine is not producing — changeovers, die swaps, tooling changes, cleaning cycles, planned maintenance windows, and shift handover time. They are "planned" in the sense that they are known in advance, but they still represent lost production time and therefore reduce Availability.
The nuance: time scheduled for a changeover is excluded from Planned Production Time and therefore does not affect OEE. But time spent on a changeover that runs over schedule — that excess time counts as a Loss 2 Availability loss.
Real-World Examples
- Injection moulding die change scheduled for 45 minutes, taking 78 minutes in practice — 33 minutes of Availability loss
- First-article inspection after setup taking 40 minutes instead of the planned 20 minutes
- Shift changeover communication and machine re-familiarisation taking 15 unplanned minutes
How Real-Time Monitoring Detects It
The OEE system timestamps the beginning and end of every changeover (either automatically from machine state data, or via a simple operator touchscreen input). Actual changeover duration is compared to standard time automatically. Any changeover that runs over standard is flagged immediately and contributes to the Availability loss breakdown. Over time, the data reveals which products, machines, and shift teams have the longest changeover overruns.
Improvement Levers
- SMED (Single-Minute Exchange of Die): systematic changeover analysis to convert internal setup steps to external steps
- Standardised changeover procedures and toolkits at machine side
- Visual management: colour-coded tooling, pre-staged carts, standardised first-article checklists
Loss 3: Small Stops (Idling & Minor Stoppages)
What It Is
Minor stoppages are brief, self-resolving interruptions — typically less than 5 minutes each — where the machine stops momentarily and then resumes without requiring maintenance intervention. A part jams in a conveyor, a sensor trips falsely, an operator pauses the machine to clear a tangle, a workpiece falls off a fixture.
This is the most underestimated loss in all of manufacturing. Most plants have no idea how many minor stops occur per shift because they are too brief to log manually and too frequent to remember. Plants typically discover 3–6× more minor stops than they expected when automated monitoring is first installed.
Why They Are Invisible Without Automation
A 40-second sensor trip at 10:23 AM. A 90-second part jam at 11:07 AM. A 25-second false alarm at 11:54 AM. An operator doesn't log these — they clear them and move on. By end of shift, the machine "ran all day" in the supervisor's perception. But the OEE data tells a different story: 47 minor stops totalling 62 minutes of lost production time.
How Real-Time Monitoring Detects It
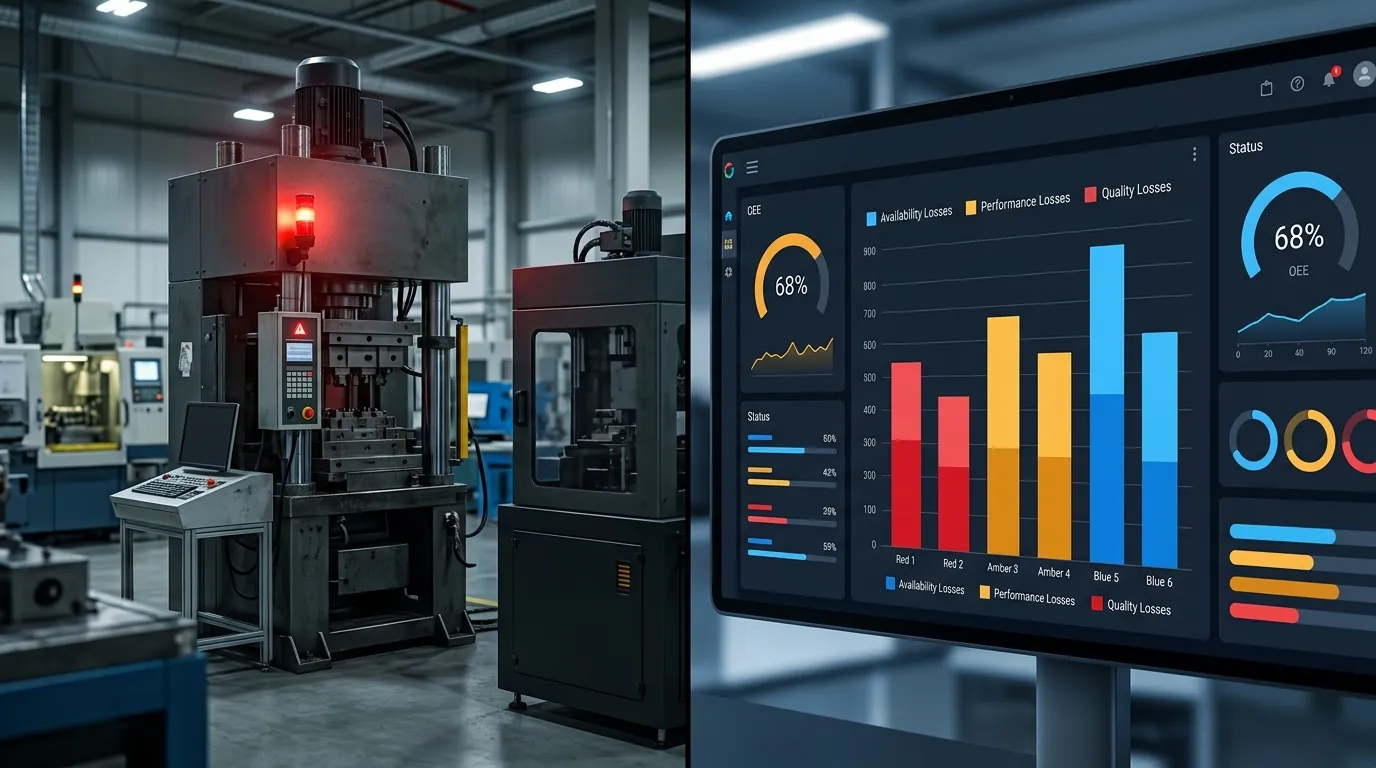
The edge gateway monitors machine state at 1–5 second intervals. Every interruption — no matter how brief — is captured as a timestamped state change. The OEE dashboard shows a Pareto chart of minor stop frequency and duration, broken down by time of day, shift, and (if reason codes are assigned) by cause type. This Pareto is typically the single most valuable output of a new OEE monitoring installation.
Improvement Levers
- Root-cause analysis of the most frequent minor stop categories (often reveals design issues with fixtures, sensors, or material flow)
- Autonomous maintenance: operators identify and eliminate minor stop sources as part of their daily routine
- Sensor calibration and false-alarm elimination
- Material flow redesign to eliminate jam points
Loss 4: Reduced Speed (Slow Cycles)
What It Is
Reduced speed loss occurs when a machine is running — producing parts — but at a throughput rate below its designed maximum. The machine looks active from the outside. No alarms are flashing. But it is quietly losing capacity every cycle.
Why It Happens
- Worn tooling: A cutting tool that needs replacement causes operators to reduce feed rate to maintain part quality
- Operator conservatism: Operators running machines below rated speed to avoid quality problems they have encountered in the past
- Process degradation: A hydraulic system with declining pressure, a spindle that vibrates above a comfort threshold
- Material inconsistency: Incoming material variability forcing cycle time adjustments
- Outdated standards: Ideal cycle time benchmarks set years ago when equipment was new, never updated as machines aged
How Real-Time Monitoring Detects It
By comparing actual cycle times (measured from sensor data: time between consecutive part outputs) against the ideal cycle time baseline, the OEE system calculates Performance in real time. A machine producing at 72% Performance means it is running at 72% of its rated speed — losing 28% of its throughput potential while appearing to be "running."
The OEE dashboard surfaces this as a Performance trend over time — revealing, for example, that Performance deteriorates progressively through a shift (consistent with tooling wear) or that it drops specifically on certain product variants (consistent with a process setup issue).
Improvement Levers
- Regular tooling replacement based on cycle-time degradation data rather than elapsed time
- Audit and refresh of ideal cycle time baselines per product and machine
- Engineering review of operator speed adjustments to distinguish legitimate quality-protection measures from unnecessary conservatism
Loss 5: Startup Rejects
What It Is
Startup rejects are scrap and rework produced during the warm-up or startup phase of production — before the process has reached thermal, pressure, or dimensional stability. These are parts that fail quality inspection on first pass, even though the machine is technically "running."
Common in Process-Sensitive Operations
- Injection moulding: first shots before mould temperature stabilises
- Die casting: first pours before die temperature reaches steady state
- Extrusion: first metres of output before melt temperature and die pressure stabilise
- Welding: first welds on cold material before wire feed and arc stability are confirmed
How Real-Time Monitoring Detects It
By flagging parts produced during the startup period (from machine-on to steady-state, identified by temperature/pressure sensors reaching target range) as "startup production," the OEE system can separately track startup reject rates per machine, per product, and per shift. This allows targeted improvement of startup procedures — reducing the number of startup rejects without changing the underlying process.
Integration with computer vision quality inspection systems can automate the classification of defects, directly feeding the Quality component of the OEE calculation without manual inspection recording.
Improvement Levers
- Standardised startup procedures that minimise warm-up time
- Pre-heating protocols for moulds and dies
- First-article inspection standardisation to reduce inspection time
Loss 6: Production Defects
What It Is
Production defects are scrap, rework, and non-conforming parts produced during normal steady-state production — after the machine has been running normally and process conditions are stable. Every defective part represents wasted material, wasted machine time, and wasted labour — and if rework is required, it typically consumes machine capacity on a second pass.
How Real-Time Monitoring Detects It
Quality data from inspection stations (automated or manual) is integrated into the OEE calculation. Every part that fails first-pass inspection reduces the Quality factor. The OEE system tracks defect rates by machine, by shift, by operator, and over time — creating a data trail that enables statistical process control analysis (SPC) to detect trends before they become rejection crises.
Improvement Levers
- Statistical Process Control (SPC): monitoring key process parameters to catch drift before it produces defects
- Automated computer vision inspection: catches defects that manual visual inspection misses, in real time
- Root-cause analysis using OEE loss data to identify which machines, shifts, and conditions produce the highest defect rates
The Hidden Distribution of Losses: What Most Plants Discover
When manufacturers install automated OEE monitoring for the first time, the distribution of losses almost always surprises them. The conventional assumption is that breakdowns (Loss 1) are the biggest problem — they are dramatic and memorable. The data typically reveals a very different picture:
| Loss Category | Expected (Management Perception) | Actual (When Automated Data Is Collected) |
|---|---|---|
| Unplanned Stops (Breakdowns) | 40–50% of losses | 15–25% of losses |
| Planned Stops (Changeovers) | 20–30% of losses | 15–20% of losses |
| Small Stops (Minor Stoppages) | <10% of losses | 30–45% of losses |
| Reduced Speed | <10% of losses | 10–20% of losses |
| Quality Losses (Losses 5 & 6) | 10–15% of losses | 5–15% of losses |
The implication is important: most plants spend most of their improvement energy on breakdowns (the most visible loss) while minor stops (the largest actual loss) go almost entirely unaddressed. Automated OEE monitoring corrects this misallocation of improvement effort.
From Loss Identification to Improvement Action
The Six Big Losses framework is only valuable if it drives action. The workflow should be:
- Install automated OEE monitoring to collect accurate, unbiased loss data
- Run Pareto analysis on loss categories after 2–4 weeks of data
- Identify the top loss category by total production time lost
- Run root-cause analysis on the top loss (why is this happening? On which machines? On which shifts?)
- Implement one targeted improvement and track whether it moves the OEE needle the following week
- Repeat — move to the next loss category once the first is controlled
This focused, data-driven approach consistently outperforms broad improvement programmes that try to address multiple loss types simultaneously. Reducing the top loss category by 50% typically has more OEE impact than making modest improvements across all six categories simultaneously.
Start Tracking All Six Losses Automatically
AdaptNXT's OEE & Machine Monitoring System automatically classifies production time into all Six Big Loss categories using sensor data from your machines — including minor stops that manual tracking will never capture. It works on legacy machines without PLC modifications. Learn how in our guide: How to Monitor OEE on Legacy Machines Without Touching Your PLCs →
See how a Tier-1 auto parts manufacturer used this approach to move from 58% to 78% OEE: Read the case study →
Speak to our IIoT engineers about monitoring the Six Big Losses on your factory floor →
Frequently Asked Questions
What is the primary benefit outlined here?
The main benefit is significant operational efficiency and cost reduction through structured implementations.
How long does implementation take?
Implementation timelines vary based on scope, but initial pilots can often show results within a few weeks.
Is this applicable to small businesses?
Yes, the principles and frameworks discussed scale from small businesses to large enterprises.